
Introduction
Ever wondered what really goes wrong when precision drops by a hair—yet costs jump by a mile?
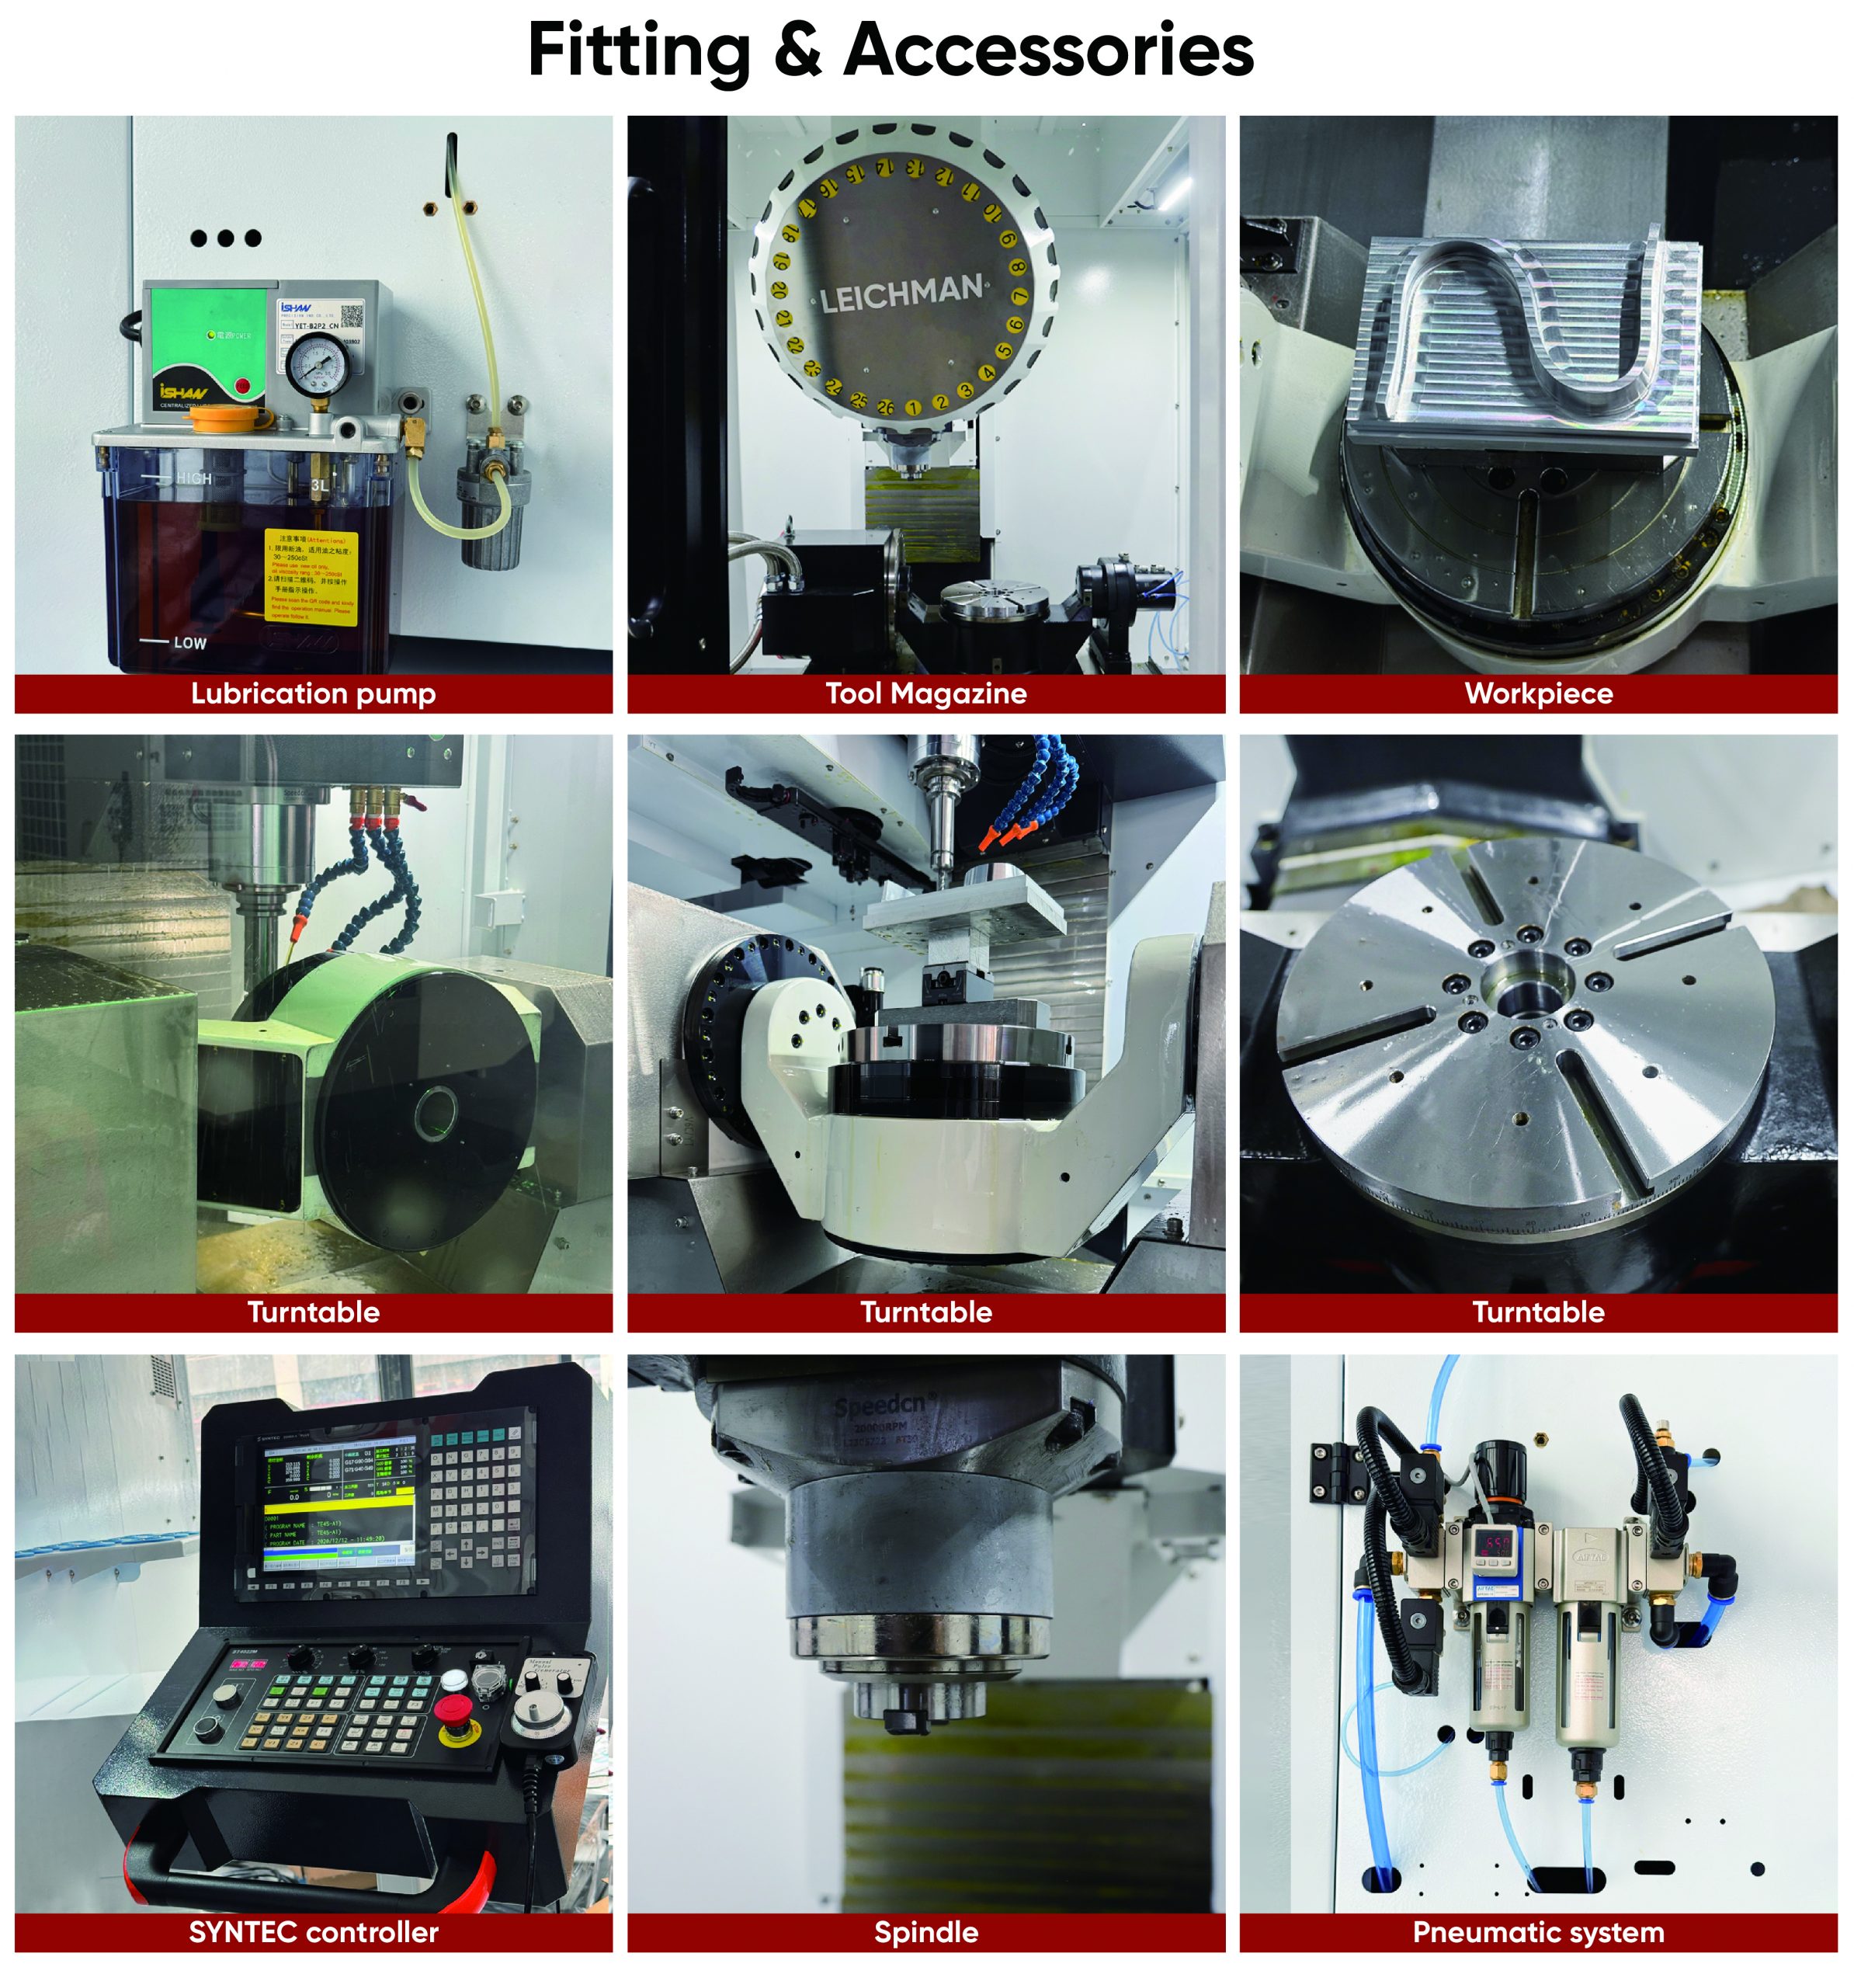
Across the board, 5 axis machining center manufacturers are reporting thinner margins and tougher delivery windows; recent shop-floor surveys put unplanned downtime at roughly 12–18% of productive hours (a number that still surprises some managers). I’ve seen this in small shops and larger plants: a missed tolerance here, a delayed shipment there. So what choices actually move the needle—preventive maintenance, higher-spec components, or smarter process controls? Let’s unpack the trade-offs and the real stakes, step by step, and see what sensible options remain. — onward to the specifics.
Deep Problem: Why Traditional Fixes Fail
cnc multi spindle machine — the idea sounds straightforward: more spindles, more throughput, quicker cycle times. Technically, that’s correct. But when you add spindles, you also multiply variables: spindle load, thermal expansion, and dynamic balance. We often think simply beefing up a machine or increasing lubrication schedules will fix the issue. It rarely does. Faults hide in controls, servo drive tuning, and in how the tool changer is managed under a high-duty cycle. Look, it’s simpler than you think: you can’t treat dynamics and electronics as afterthoughts.
What fails in traditional approaches is a layered mismatch. First, maintenance tends to be reactive: replace worn parts when they fault. Second, shops standardize on parts that are “close enough” rather than matched to the power converters and control firmware. Third, process planning often ignores thermal drift across a long cycle—so initial setup looks perfect, but repeatability degrades. From a user’s view, these are hidden pain points: sporadic chatter, subtle roundness errors, and intermittent tool wear that baffles operators. I’ve watched teams chase symptoms for weeks while root causes sat in the control stack or in improperly calibrated spindle sensors. In plain terms: better components alone won’t eliminate variability without comms tuning and aligned maintenance strategy.
What’s the core issue?
It’s integration: mechanical design, electronics, and software must be tuned together. Is your spindle monitoring talking confidently to your CNC? Are your edge computing nodes—or local PLCs—reporting anomalies fast enough? If not, you only mask failure modes, you don’t prevent them.
Looking Ahead: New Paths and Practical Choices
Now let’s look forward. I prefer a practical lens: hybrid solutions that combine smarter sensors, predictive analytics, and modest hardware upgrades. For example, retrofitting condition monitors and integrating them into the control loop reduces unexpected spindle failures. Pair that with process optimization—shorter non-cutting moves, adaptive feed rates—and you can improve part consistency without doubling investment. Also consider newer designs of high speed cnc machining centers that balance rigidity with thermal control; they cost more up front but lower total cost of ownership over time. Seriously—funny how that works, right?
In practice, I advise a staged approach. Begin with baseline metrics: cycle time variance, scrap rate, and mean time between failures. Add targeted upgrades—better servo tuning, a calibrated tool changer, or a closed-loop spindle speed control—then measure again. Short experiments give you real data, not opinions. Over time, you’ll see whether the new setup just improves throughput or actually yields tighter tolerances and fewer operator interventions. — small steps, measurable gains.
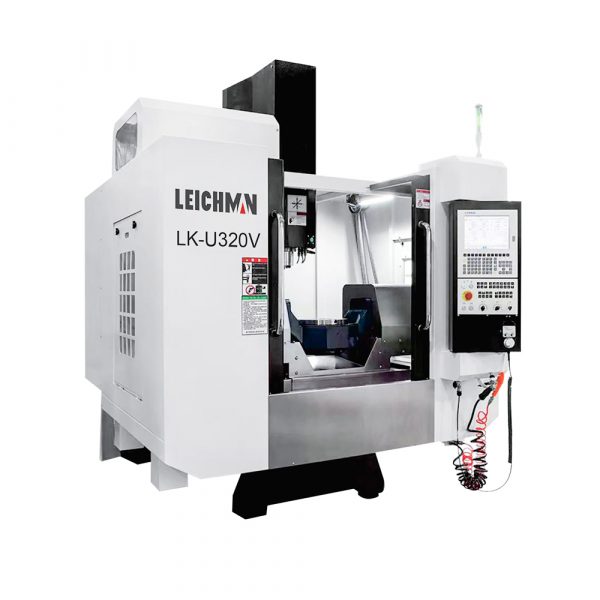
What’s Next?
If you’re deciding now, prioritize three evaluation metrics I use when I consult with shops:
1) Variance Reduction: Track standard deviation in cycle time and in critical dimensions before and after any change. That shows real control improvement.
2) Failure Predictability: Measure how often condition monitors produce actionable alerts versus false positives. A system that cries wolf wastes time.
3) Throughput per Dollar: Compare net parts produced divided by total lifecycle spend (maintenance + energy + downtime). This gives a clear ROI picture.
To wrap up, I’ll be blunt: upgrades and smart monitoring work, but only when paired with disciplined measurement and an honest assessment of hidden costs. We—designers, managers, and operators—need to move from “fix it when it breaks” to “prevent what we can predict.” That requires modest investment in sensors, better integration between control and power systems, and a willingness to test changes incrementally. If you want an example of a vendor that combines these elements with practical support, check Leichman — they build systems that make these trade-offs visible and manageable. I’ve used similar approaches in the field; they’re not glamorous, but they win in the end.